Student Support LLM Platform
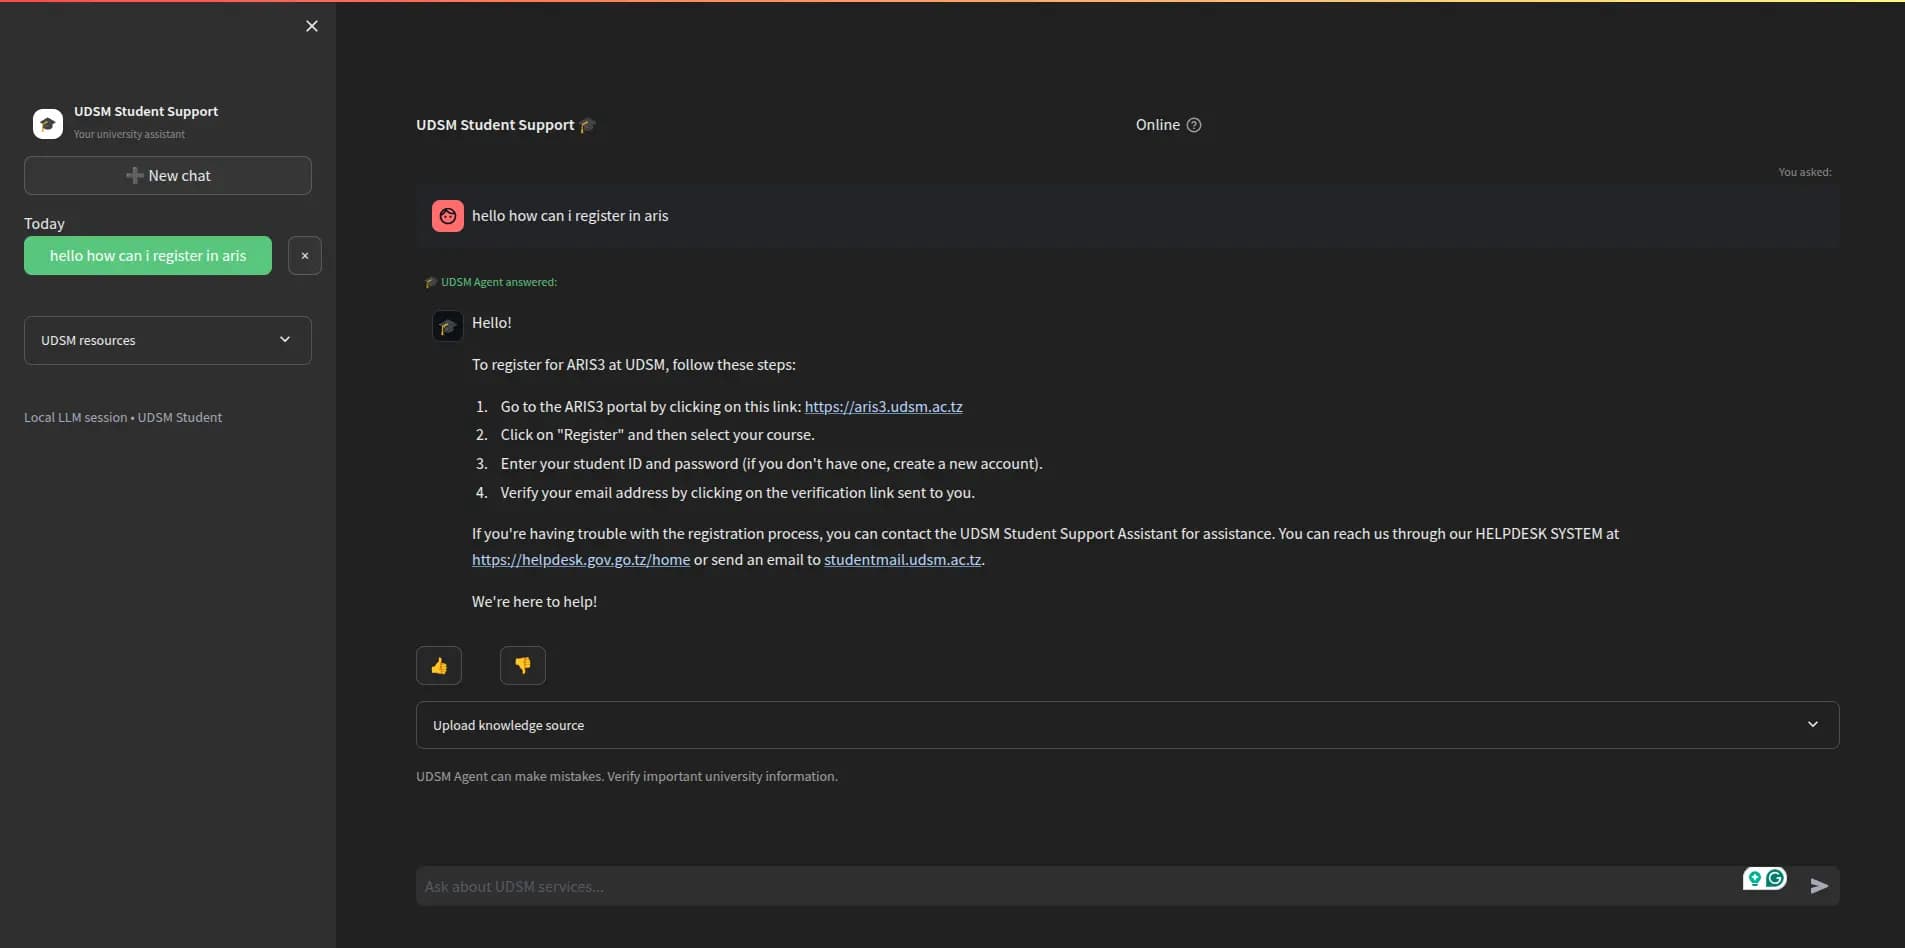
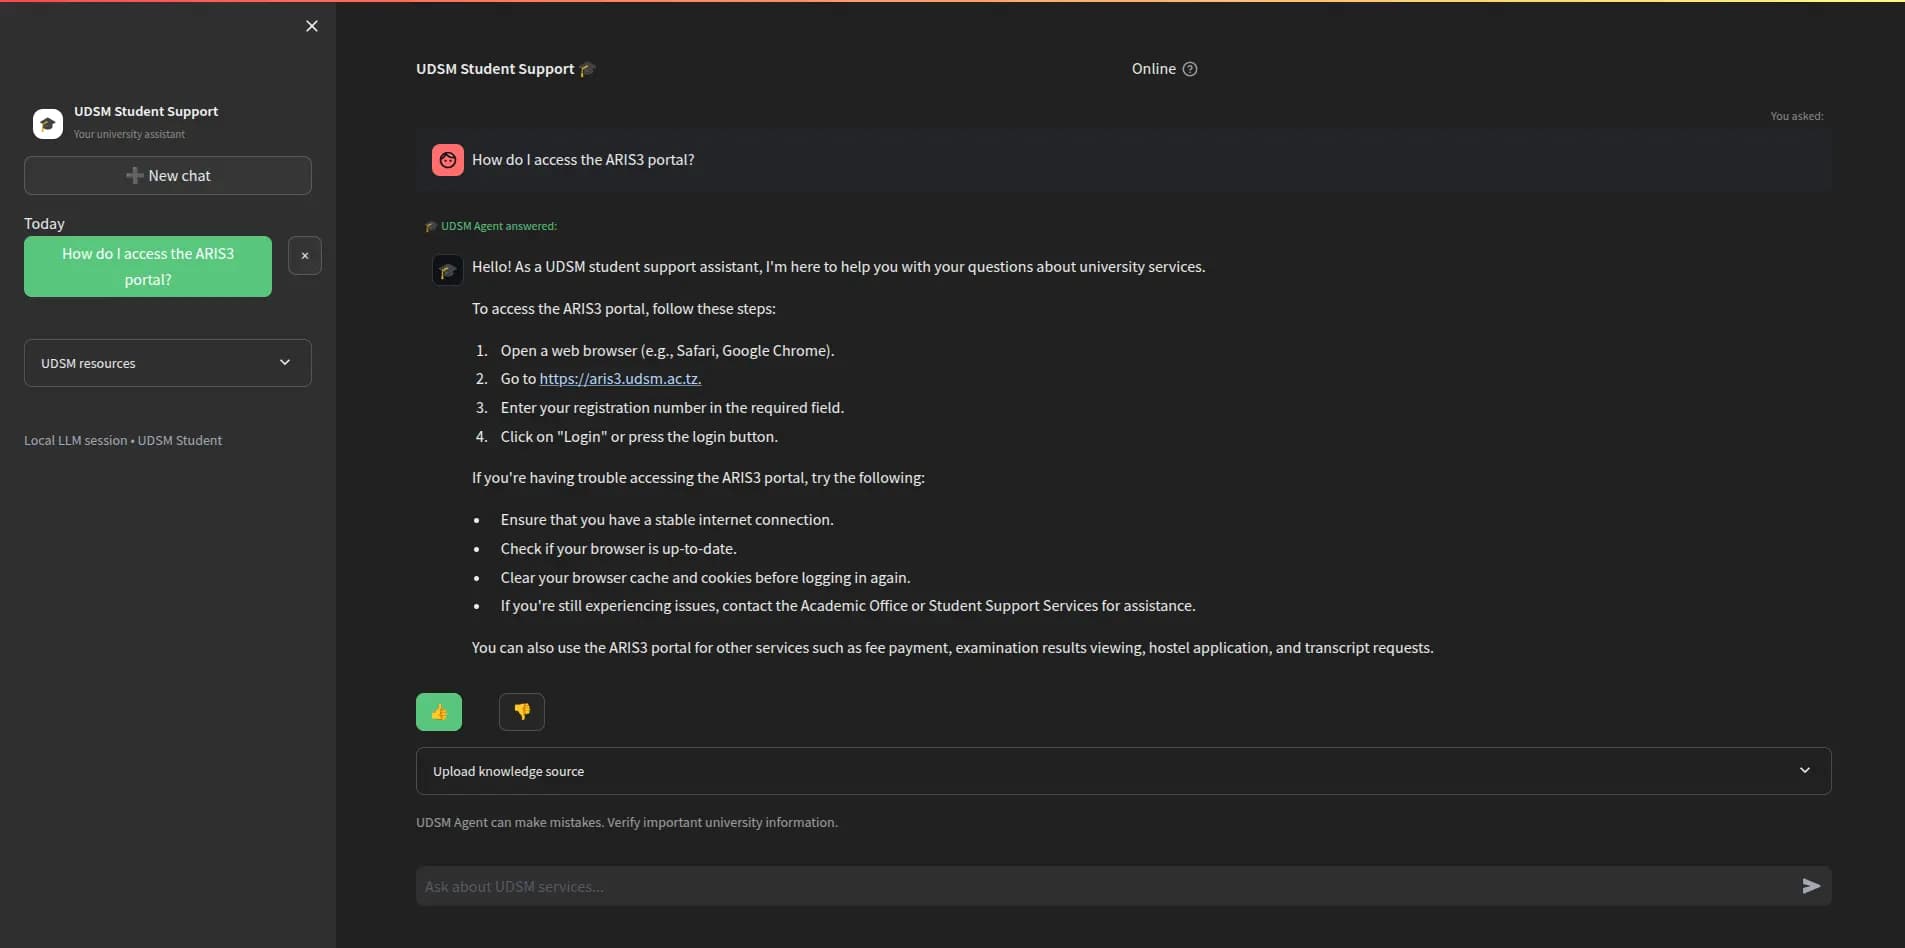
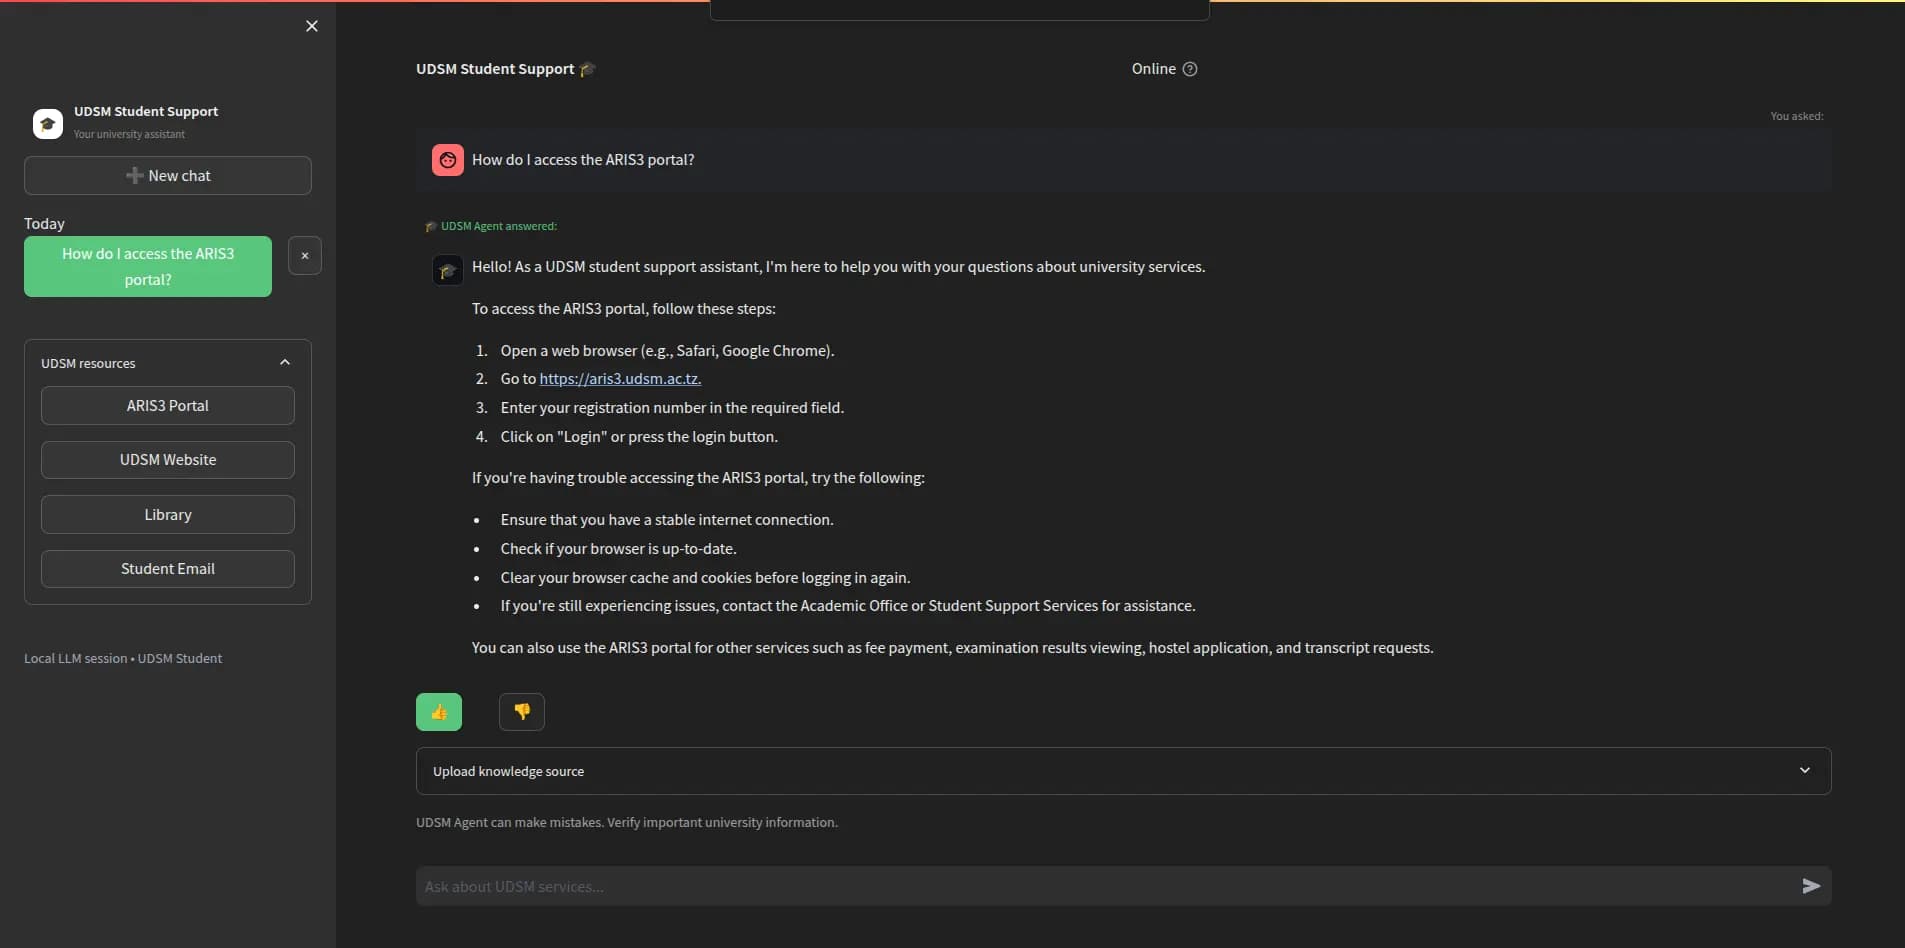
A locally hosted AI-powered student support assistant developed to provide conversational academic guidance while demonstrating the complete deployment pipeline of an LLM-based application.
- Role
- Full-Stack Developer & AI Integration Developer
- Organisation
- Independent / academic
- Status
- Academic Project
- Period
- 2026
Case study
Problem, solution and contribution
The problem
Students need a convenient way to access common academic guidance, while the academic assignment required an understanding of how a local language model, backend and frontend communicate.
The solution
A local AI application in which a Streamlit interface sends requests to a FastAPI backend, which communicates with an Ollama-hosted language model and a custom knowledge base.
My contribution
- Designed the frontend-to-model request pipeline
- Implemented the FastAPI backend and API contracts
- Built the custom FAQ knowledge base
- Integrated the Retrieval-Augmented Generation pipeline
- Added logging and testing
- Documented production-readiness improvements
Intended users
Students seeking quick, reliable answers to common academic questions.
Chat-style user interface
Local model inference
Custom university FAQ knowledge base
Retrieval-Augmented Generation
API-based frontend and backend communication
Logging and testing
Privacy-conscious local deployment
Documented production-readiness improvements
Architecture
The application demonstrates a full local LLM pipeline where each layer communicates over clear API boundaries. No external paid AI API is used. Inference runs locally through Ollama.
- User → Streamlit frontend
- Streamlit → FastAPI backend
- FastAPI → RAG retrieval
- RAG → Ollama local model
- Model → generated response
- Response → frontend display
Retrieval-Augmented Generation
A custom university FAQ knowledge base is retrieved and injected into prompts so answers stay relevant and grounded, while keeping all data on local infrastructure.
Production readiness
The assistant was built as a learning-focused deployment, with logging, testing and a documented list of improvements needed to move it toward production.
Product gallery
Screens and supporting visuals
Outcome
Demonstrated an end-to-end, privacy-conscious local LLM deployment with grounded, knowledge-base-driven responses.